Machine learning · Jul 2024
Multilingual RAG System
Retrieval-augmented question answering over PDF documents and books, with support for questions across languages.
Overview
Asking questions across documents and languages
Large PDFs and books can be difficult to navigate when someone needs a specific answer. That becomes harder when the question and the source material use different languages.
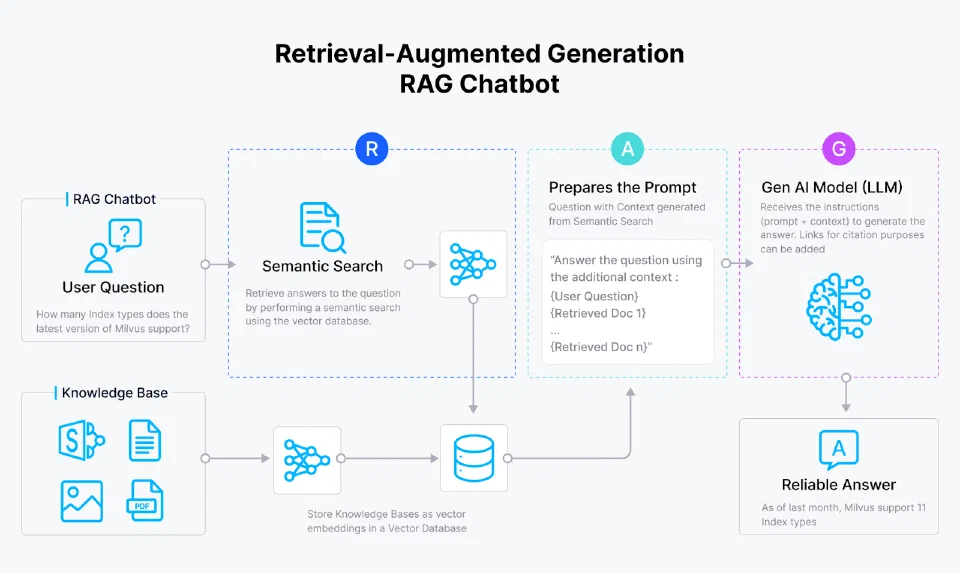
This project combines document search with language-model generation. It retrieves relevant passages first, then uses that context to support an answer rather than relying only on the model’s existing knowledge.
Technical detail
The pipeline combines PDF text extraction, OCR for image content, text splitting, Hugging Face embeddings, and FAISS retrieval through LangChain. Sample material spans Bengali, English, Urdu, and Chinese.
Chunking and retrieval shape the context available to generation: larger chunks preserve surrounding material but consume more context, while smaller chunks can separate related information. The project explores those choices as part of a multilingual question-answering workflow.